Flawless Grammar but Mental Fatigue? Martin Fowler on 'LLM Voice': Syntactic Flattening, Cognitive Drag & Defending the Right to Think
深度拆解软件工程大师、《重构》作者 Martin Fowler 重磅发声《LLM Voice》:剖析技术博客、开源文档与架构提案中普遍蔓延的“文字恐怖谷”。结合纽约大学心理语言学与《Nature Human Behaviour》88 万篇实证数据,揭示机器生成文本在微观句法过度压缩与宏观观点稀薄之间的剧烈反差;解析 Hacker News 580+ 高热争议,并提炼 Fowler 拒绝模型撰写初稿的个人铁律与面向工程团队的三步审稿落地法。
A comprehensive breakdown of software engineering icon and 'Refactoring' author Martin Fowler's timely essay 'LLM Voice'. We unpack the Uncanny Valley of text spreading across RFCs, open-source docs, and technical blogs. Combining psycholinguistic research from NYU/UT Austin and an 880,000-text Nature Human Behaviour empirical study, we dissect why machine-generated prose creates severe cognitive fatigue through syntactic over-compression and macro insight dilution. Exploring the 580+ point Hacker News debate, we detail Fowler's core thesis—writing is the engine of thinking—and present a 3-step peer-review protocol for engineering teams.
大家好 我是为什么叫QQ
Hello everyone, I'm WhyQQ.
平时看技术博客
When reading technical blogs,
开源项目文档或者团队内部的架构提案时
open-source project docs, or internal architecture proposals,
许多工程师都遇到过一种奇特的阻滞感
many engineers have experienced a peculiar feeling of friction.
文章开头两段条理顺畅 语法挑不出半点毛病
The opening paragraphs read smoothly with impeccable grammar,
段落之间还有工整的小标题和排比总结
structured with neat subheadings and parallel bullet points.
可一旦读到第三段 注意力就开始迅速涣散
Yet by paragraph three, your attention span rapidly unravels,
直接关掉页面
tempting you to simply close the tab.
哪怕耐着性子读完
Even if you force yourself to read to the end,
合上电脑也很难复述出作者的核心技术判断
closing your laptop leaves you struggling to recall the author's core technical thesis.
2026年10月29日
On October 29, 2026,
软件工程界极具分量的作者Martin Fowler在
Martin Fowler, one of software engineering's most influential authors,
个人博客发表了一篇题为《LLM Voice》的文章
published an essay on his blog titled "LLM Voice",
专门命名并探讨这种阅读疲劳
coining and dissecting this exact cognitive fatigue.
跳过市面上常见的AI文本检测套路
Bypassing typical commercial AI detection gimmicks,
今天我们从句法结构 认知负荷与工程实践的角度
today we unpack this phenomenon through syntactic structure, cognitive load, and engineering practice,
探讨大模型生成的文字让人越读越累的底层机制
exploring the root mechanics of why LLM-generated prose feels so exhausting to read.
提起Martin Fowler 写代码的同行都很熟悉
Developers worldwide know Martin Fowler well.
他在Thoughtworks担任首席科学家
As Chief Scientist at Thoughtworks,
撰写的《重构》和《企业应用架构模式》
his seminal books, "Refactoring" and "Patterns of Enterprise Application Architecture",
几乎是后端与架构师的案头必读书
remain essential reading for backend developers and architects alike.
几十年来 他一直在个人网站上用平实
For decades, he has used clear, rigorous prose
严谨的语言把复杂的软件
on his personal site to distill complex software engineering design
设计经验沉淀为工程共识
into widely adopted industry consensus.
他长期活跃在技术一线
Staying active on engineering frontlines,
对各类提升研发效率的工具始终抱有开放态度
he has always maintained an open attitude toward developer productivity tools.
在这篇讨论AI写作的文章末尾
At the conclusion of this essay on AI writing,
Fowler特意留下了一行声明:
Fowler appended an emphatic disclosure:
全文没有任何一个字使用过AI或大语言模型
Not a single word in the article was produced with the help of AI or LLMs.
一位长年依靠文字传递工程思想的技术作家
For a seasoned technical writer who built a career conveying engineering thought,
选择在这个时间点呼吁克制使用生成式写作
calling for restraint against generative prose at this moment
背后指向了一个核心冲突:
highlights a fundamental tension:
流畅生成文本的能力 与高效传递思想的能力
The capacity to fluently generate text and the ability to efficiently convey thought
完全处在两个不同的维度
exist on two entirely separate planes.
很多人在社区里看到疑似AI生成的帖子
When encountering suspected AI content online,
第一反应是找破折号 三段式加粗列表
many look for em-dashes, bolded three-part bullet lists,
或者检索delve meticulous这类高频词
or search for stereotypical buzzwords like "delve" or "meticulous".
Fowler在文章里明确提醒
Fowler explicitly cautions in his essay
依靠标点符号或特定词汇来抓AI极不可靠
that policing punctuation marks or vocabulary lists is utterly unreliable.
他甚至怀疑自己能否准确
He doubts whether even he could reliably identify
分辨每一篇机器生成的文章
every single piece of machine-generated text,
更不赞成把AI检测工具当成解决方案
and firmly rejects treating AI detectors as a viable solution.
人类自身的语言习惯本就在不断演变
Human linguistic patterns naturally evolve over time.
真正引发不适的根源
The true source of cognitive friction
在于整篇文章呈现出的一种高度同质化的腔调
stems from the pervasive, homogenized tone saturating the entire piece.
每一个单句在语法规则上都完备无缺
Every isolated sentence is grammatically flawless,
连缀成篇后却找不到真实作者的取舍
yet strung together, they reveal none of an author's real trade-offs,
犹豫与独特视角
hesitations, or personal perspective.
Fowler将这种体验定义为文字的恐怖谷:
Fowler terms this experience the Uncanny Valley of text:
外观极度逼真 内核却缺乏人类的真实触感
a surface strikingly lifelike, yet hollow of authentic human texture.
结合技术社区的大量反馈
Reflecting broad consensus across engineering communities,
这种被称为LLM Voice的
this style known as "LLM Voice"
文风通常带有四个显著特征
typically exhibits four distinct hallmarks:
第一 喜欢把一个具体的
First: inflating specific, small technical problems
工程小问题包装得无比宏大 动辄上升到行业范式
into grandiose narratives, routinely framing minor tweaks as industry paradigm shifts.
第二 极其偏爱转折与拔高
Second: an obsession with rhetorical pivots and crescendo conclusions,
仿佛每一个自然段的结尾
as if every paragraph must conclude
都必须敲定一个金句或结论
with an authoritative aphorism or grand takeaway.
第三 句式节奏高度雷同 即便去掉了项目符号
Third: rigidly uniform syntactic cadence; even without bullet markers,
读起来依然像一串机械排列的要点清单
the prose still reads like a mechanical list of checklist items.
第四 上下文经常出现同义反复
Fourth: rampant contextual tautology—
用不同的词藻把前文刚讲过的概念再解释一遍
re-explaining concepts introduced moments earlier using slightly varied vocabulary.
有时还会把提示词里的
Occasionally, fragments of prompt instructions
任务指令痕迹直接带进正文
bleed straight into the body text,
读起来像在向模型交差
reading like a perfunctory compliance report to an evaluator.
需要说明的是
It is worth clarifying:
这些现象属于读者群体的阅读体验归纳
these observations summarize reader experiences across communities,
并非严格的算法检测标准
rather than formal algorithmic detection benchmarks.
阅读疲劳感有着扎实的心理语言学依据
This reading fatigue is grounded in solid psycholinguistic evidence.
2026年10月21日
On October 21, 2026,
来自纽约大学与德克萨斯大学奥斯汀分校
a research team from NYU and UT Austin
的研究团队在arX iv发表了一篇预印本论文
published a preprint on arXiv
专门测量AI生成语言理解困难的成因
investigating why AI-generated language induces cognitive processing strain.
研究人员对比了9个前沿及近
Comparing 9 frontier and near-frontier LLMs
前沿大模型与人类真实文本
against authentic human writing,
发现模型生成的句子显著高频地包含五类结构:
they found AI sentences significantly over-index on five structural traits:
无生命主语搭配有生命动词 低频词组组合
inanimate subjects with animate verbs, rare collocations,
更长的句法依赖距离 密集的名词堆叠
extended syntactic dependency distances, dense noun stacking,
以及缺少显式引导词的关系从句
and relative clauses stripped of explicit connective markers.
这就好比我们在做代码审查时
This mirrors code review scenarios where you encounter syntactically valid code
遇到一段语法合法但把五层
that forcibly crams five levels of business logic
逻辑强行塞进一行表达式的代码
into a single-line nested ternary expression.
句法没有报错 但人类大脑在解析语法树时
The parser emits no errors, but the human brain parsing that AST
需要消耗额外的短期工作记忆
must burn disproportionate short-term working memory.
造成这种句法差异的原因
The root cause of this syntactic divergence
与两套截然不同的优化目标有关
lies in two fundamentally conflicting optimization targets.
人类日常写文章做沟通
In human communication,
首要目标是确保对方顺畅理解
the primary objective is ensuring effortless reader comprehension,
因此会主动控制信息释放的节奏
leading authors to regulate information pacing
加入必要的逻辑过渡
and insert natural transitional breathing room.
反观大语言模型 在经历大量数学
In contrast, LLMs trained extensively on mathematics,
代码与复杂推理任务的训练时
code, and chain-of-thought reasoning
往往承受着在更少Token内
operate under continuous pressure to compress maximum semantic information
压缩更多信息的优化压力
into minimal token budgets.
研究团队在Qwen 2. 5-1.5B模型上
When researchers applied RL fine-tuning with length penalties
引入长度惩罚进行强化学习微调后
to the Qwen 2.5-1.5B model,
清晰观察到模型开始偏向更短
they observed a distinct drift toward shorter,
句法更紧绷的表达结构
syntactically denser, and more strained sentence structures.
当然 这项新发布的预印本仍属于机制假说
Naturally, this preprint remains an explanatory hypothesis;
并且研究也发现Opus 5.5在21项阅读
notably, the study also found that Opus 5.5 improved on 19 out of 21
困难指标中有19项比Opus 5出现了改善
processing difficulty metrics compared to Opus 5,
说明模型表达质量可以通过针对性优化得到缓解
proving that output prose quality can be meaningfully alleviated through targeted training.
如果仅仅是机器直接生成的文章难读
If it were merely machine-authored posts that were tiring to read,
我们还可以选择关掉页面
we could simply navigate away.
更深远的变化在于
The more profound shift underway
人类作者自己的行文风格正在被悄悄抹平
is that human writers are having their own expressive voices quietly erased.
2026年发表于《Nature Human Behaviour》的一项重磅研究
A landmark 2026 study in Nature Human Behaviour
横跨7个数据集 3项独立子研究
spanning 7 datasets and 3 independent empirical studies
分析了超过88万篇真实文本
analyzed over 880,000 real-world texts.
数据表明 随着大语言模型普及
The data revealed that with the widespread adoption of LLMs,
多个写作平台的语言复杂度差异出现明显回落;
stylistic diversity variance across multiple publishing platforms dropped dramatically.
当不同作者使用模型润色自己的原稿后
When diverse authors relied on LLMs to polish their drafts,
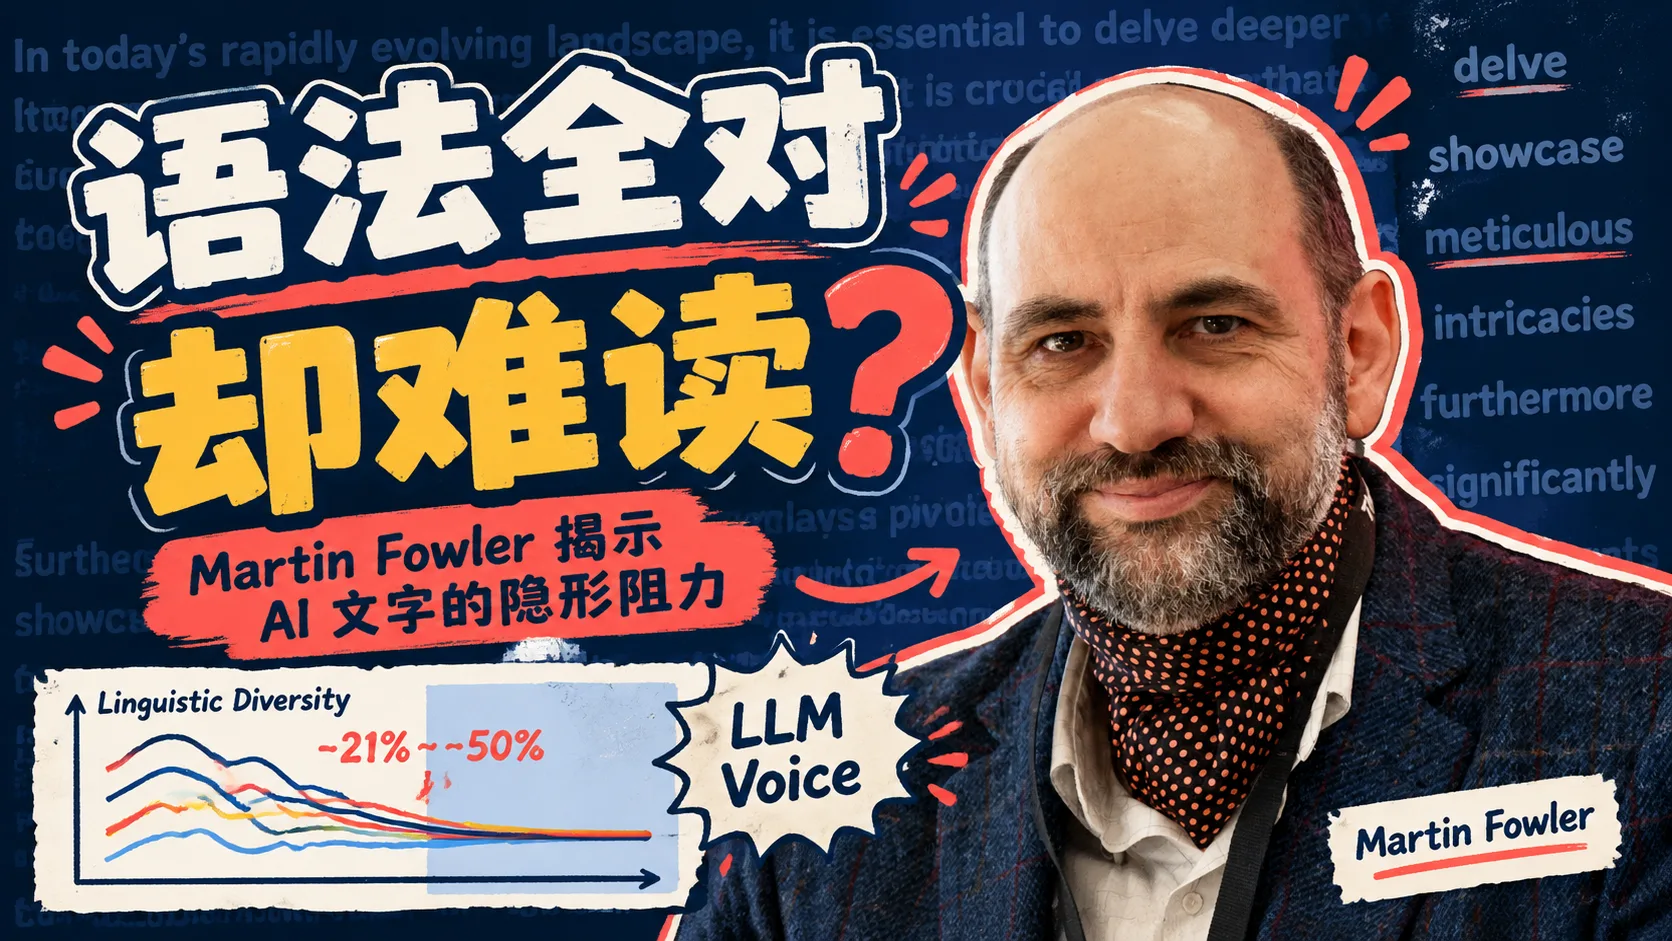
群体的写作复杂度方差下降了21% 到50%
the cohort's writing complexity variance collapsed by 21% to 50%.
与此同时 约87%的改写文本与原稿的
Meanwhile, roughly 87% of rewritten passages retained
语义嵌入相似度依然保持在0.95以上
semantic embedding similarities above 0.95 with the originals.
文章原本想传达的业务含义基本没变
The underlying message remained superficially intact,
但不同作者之间鲜明的个人表达习惯
yet the distinct, idiosyncratic voices of individual authors
正在坍缩成同一种标准模板
were flattened into a single, standardized corporate template.
这种风格的同质化已经跨越了屏幕
This linguistic homogenization has leaped from screen to speech,
开始渗透进人类的日常口语交谈
quietly infiltrating everyday spoken conversations.
另一项在2026年更新的实证研究
Another empirical study updated in 2026
扫描了824,634期播客节目
scanned 824,634 podcast episodes,
总计覆盖737083小时未经脚本设计的自然对话
encompassing 737,083 hours of unscripted, natural dialogue,
并配套开展了496名参与者的预注册对照实验
paired with a pre-registered controlled experiment of 496 participants.
统计曲线显示 自ChatGPT问世以来
Statistical trajectories showed that since ChatGPT's debut,
模型偏爱的词汇如delve showcase
model-favored words like "delve", "showcase",
boast intricacies和meticulous
"boast", "intricacies", and "meticulous"
在人类脱稿聊天的自然语音中出现频率显著攀升
skyrocketed in spontaneous human speech.
实验室测试进一步证实
Controlled trials further established that
参与者哪怕只是与聊天机器人进行短暂的互动
even brief interactions with a chatbot prompted participants
在随后的口头交流中也会
to unconsciously adopt and mirror
不自觉地借用机器人的高频措辞
the machine's high-frequency vocabulary in subsequent verbal discourse.
人类在高频调用模型生产内容的同时
As we lean heavily on models to produce prose,
大脑的语言词库也在被模型反向塑造
our cognitive linguistic lexicon is being inversely shaped by the model.
遵循严谨的工程分析习惯
Practicing disciplined engineering analysis,
我们同样需要审视方向不同的科学证据
we must examine counterbalancing scientific findings.
在ACL 2025收录的一项研究中
In a study published at ACL 2025,
学者对比了2018年与2024年的英语新闻报道
scholars compared English journalism between 2018 and 2024.
结果显示 虽然部分具有AI风格特征的词汇指标有所抬头
While certain AI-associated lexical markers rose,
但研究采用的两项整体词汇
two overarching lexical diversity indices
多样性统计指标并未出现显著下滑
showed no statistically significant degradation across the corpus.
不同语料库 时间跨度与统计
Varying corpora, timeframes, and measurement frameworks
口径会得出存在差异的结论
yield nuanced, sometimes divergent conclusions.
因此不能草率断言所有领域的
It is premature to declare that human linguistic diversity
人类语言多样性都已经全面衰退
has suffered across-the-board collapse in every domain.
把这几项研究放在一起观察
Synthesizing these findings brings a striking paradox into view:
能发现一个非常耐人寻味的反差:
one uncovers a deeply intriguing contrast:
AI文本在宏观内容上常常车轱辘话连篇
At the macro level, AI prose often dilutes meaningful insight with circular filler;
有效观点稀薄;
substantive arguments remain sparse.
在微观句法上却又过度压缩 生造名词堆叠
Yet at the micro level, it over-compresses syntax with dense noun clusters.
篇幅冗长与句法高密度同时并存
Bloated length and strained density coexist simultaneously,
双重拉高了阅读成本
doubly amplifying the reader's cognitive burden.
Fowler的文章在Hacker News上拿下了超过580分的高热度
Fowler's essay soared past 580 points on Hacker News,
引发了三百多条长评交锋
sparking over 300 intensive debates.
不少平时重度使用AI编程工具的拥护者也坦承
Many ardent proponents of AI coding assistants openly conceded
现在看到带有明显生成痕迹的长文往往读到一半就想退订
that encountering overt AI prose now triggers an immediate urge to unsubscribe halfway through,
因为模型太喜欢用毫无必要的否定转折
because models rely so heavily on gratuitous rhetorical pivots,
把每一句话都写得像重大发现
treating every trivial remark as an earth-shattering epiphany.
与此同时 社区里也出现了重要的补充视角:
At the same time, the community contributed crucial balance:
许多开发者指出
many engineers noted that
对于非英语母语的工程师 语言障碍人士
for non-native English speakers, neurodivergent developers,
或者需要处理跨国协作邮件与格式化工单的场景
or teams handling cross-border support emails and standardized tickets,
大模型的翻译和辅助润色提供了实打实的帮助
LLM translation and assistive polish deliver tangible, indispensable leverage.
更有人提醒 千万不要把
Others rightly warned against mistaking
非母语者略显生硬的语法
a non-native author's earnest phrasing
或者部分人群严谨刻板的写作习惯误判为AI水文
or a deliberately precise, dry writing style for generative fluff.
区分辅助沟通与替代思考 才是讨论的核心
Distinguishing communication assistance from outsourced thinking is the crux of the debate.
面对这种趋势
Confronting this reality,
Fowler给出了几条相当严格的个人准则:
Fowler articulates several uncompromising personal rules:
永远不要让大模型替你写文章的第一稿;
Never let an LLM write the first draft of an article;
即便只让模型提供单句改写 也要保持高度警惕;
Remain fiercely vigilant even when asking a model to rephrase single sentences;
大纲梳理和资料检索可以借助AI
Leverage AI freely for outline exploration and literature search,
但每一个正文字句必须由自己敲出
but draft every single sentence of the manuscript yourself;
所有引用的资料必须回溯到原始出处进行核实
and verify every cited reference directly against its primary source.
他只把残障辅助 多语言翻译 固定格式信函以及
He carves out exceptions only for accessibility assistance, multilingual translation, formulaic boilerplate,
根本没人看的流程性报告列为例外
and bureaucratic compliance reports that nobody ever reads.
在习惯了凡事让AI生成一版草稿的今天
In an era where default behavior is asking AI for a quick draft,
这套做法看似有些保守
this approach might appear conservative,
却切中了认知心理的要害:
yet it strikes at the core of cognitive psychology:
一旦让模型先生成了初稿
The moment you allow an AI model to draft the initial text,
它的行文框架和句式节奏
its framing, structural rhythm, and assumptions
就会形成强烈的锚定效应 后续无论怎么人工涂改
cast an overwhelming anchoring effect; no amount of later editing
都很难彻底洗掉那股统一的机器腔调
can fully purge that uniform synthetic cadence.
整篇文章最触动工程师群体的部分
What resonated most deeply with engineers
在于Fowler对写作本质的剖析
is Fowler's dissection of what writing fundamentally is.
他坦言 写作向来是自己
He explains that writing has always served as his primary cognitive engine
弄清楚复杂问题的核心工具
for making sense of complex, thorny problems.
很多时候动笔之初 脑海里只有一个模糊的直觉;
When starting a piece, you often possess merely a hazy intuition;
恰恰是在亲自挑选词汇 推敲段落衔接
it is precisely through selecting words, wrestling with transitions,
反复删改逻辑的过程中
and iteratively rewriting logical flows
原本隐藏的思维漏洞才会被迫暴露出来
that hidden flaws in your thinking are dragged into the light,
观点也随之逐渐成型
forcing your technical judgment to mature.
这与我们日常写代码的过程高度同构
This process is completely isomorphic to writing software.
在AI Coding普及的当下
With modern AI coding workflows,
让Agent在十秒内生成五百行能跑通的代码很容易
prompting an agent to generate 500 lines of functional code in ten seconds is effortless;
但生成了代码绝不等于你真正吃透了系统的边界条件与架构代价
yet generating code is not equivalent to understanding boundary conditions and architectural trade-offs.
如果把从零组织语言的过程完全跳过
If you bypass the cognitive labor of structuring language from scratch,
表面上看是省下了码字的时间
you save typing minutes on the surface,
实际上却一并跳过了深度思考与建立判断的过程
while entirely skipping the vital process of deep thinking and forming conviction.
在日常撰写技术设计文档
When authoring architecture RFCs,
故障复盘报告或技术博客时
post-mortem incident reviews, or engineering blogs,
我们可以借鉴代码审查的思路
we can borrow the discipline of code reviews:
把AI从代笔者改造成严格的审稿人
repositioning AI from a ghostwriter into an unsparing peer reviewer.
第一步 哪怕语句粗糙或者直接用语音输入
Step 1: Even with rough notes or voice transcription,
也先由自己把核心问题
write out the core problem yourself,
架构取舍和真实案例写出来
documenting architectural trade-offs and authentic case studies.
第二步 调用一套专门限制
Step 2: Employ a structured review prompt that strictly forbids
代笔行为的审稿提示词
the AI from ghostwriting,
明确要求模型只从观点清晰度
instructing it to critique solely across five dimensions:
逻辑跳跃 事实来源 冗余铺垫
clarity of argument, logical leaps, sourcing, needless fluff,
和读者流失点五个维度挑刺
and reader drop-off risks.
按高 中 低标注严重程度
Rate findings as High, Medium, or Low,
严禁模型直接重写句子或提供替代文本
explicitly banning the model from rewriting sentences or offering drop-in text,
并在最后指出你最值得保留的三个个人表达特点
while identifying three personal voice traits most worth preserving.
第三步 参考审稿意见 用自己的话亲手修改
Step 3: Review the feedback and revise the draft by hand in your own voice.
第四步 将所有论文数据与
Step 4: Trace all cited research metrics and engineering claims
技术结论回溯到一手信源核实
back to verified primary sources.
这套流程既能借力模型的检查能力
This protocol harnesses the analytical vigilance of LLMs
又能牢牢把控表达主导权
while anchoring expressive authorship squarely in human hands.
随着模型训练技术的持续迭代
As model training methods continue to evolve,
未来单凭肉眼去分辨一段话出自人类还是机器
distinguishing human prose from synthetic output with the naked eye
难度只会越来越大
will only grow increasingly challenging.
但对于软件工程师而言
Yet for software engineers,
核心竞争力从来就不在于敲击键盘的机械速度
our core competitive advantage was never typing velocity.
在工程研发中 业务代码可以交给Agent编写
In modern engineering, boilerplate logic can be delegated to agents,
自动化测试可以交给流水线执行;
and automated tests can execute inside CI/CD pipelines;
然而系统架构为何这样划分
yet why a system boundary is drawn,
不同技术方案背后的代价如何权衡
how architectural trade-offs are weighed,
我们到底要解决哪个真实问题
and which real-world problem genuinely matters
始终需要人类工程师拍板并承担责任
will always require human engineers to decide and take accountability.
写文章与写文档也是同样的道理
The exact same truth holds for writing and technical documentation.
我们可以大方地利用工具去检索文献
We can embrace tools to uncover literature,
校验逻辑漏洞 跨越语言障碍
surface logical holes, and bridge language barriers;
但请务必保留亲手组织观点 推敲表达的习惯
but we must fiercely preserve the habit of crafting arguments and weighing prose ourselves.
善用AI的力量 同时守住属于你自己的真实声音
Harness the power of AI, while fiercely guarding your own authentic voice.
感谢观看 如果本期内容对你有用
Thanks for watching! If this breakdown provided value,
记得一键三连 我们下期见
don't forget to like, subscribe, and share. See you next time!
大家好 我是为什么叫QQ
Hello everyone, I'm WhyQQ.
深度拆解软件工程大师、《重构》作者 Martin Fowler 重磅发声《LLM Voice》:剖析技术博客、开源文档与架构提案中普遍蔓延的“文字恐怖谷”。结合纽约大学心理语言学与《Nature Human Behaviour》88 万篇实证数据,揭示机器生成文本在微观句法过度压缩与宏观观点稀薄之间的剧烈反差;解析 Hacker News 580+ 高热争议,并提炼 Fowler 拒绝模型撰写初稿的个人铁律与面向工程团队的三步审稿落地法。